How to scrape job listings to Excel (free, no code)
Tracking a job search, benchmarking pay, or watching who's hiring? Turn any job-board search into a clean spreadsheet — titles, companies, locations, salaries, dates and links — free and no code.
Whether you’re running a job hunt, benchmarking salaries for your field, or keeping a live view of who’s hiring for what, the data you want already exists — it’s just sitting in a job board’s search results, one card at a time. Copying titles, companies and links by hand stops being fun after about ten postings, and writing a scraper in Python is a chunk of a Saturday for something you might run twice.
This guide shows you how to scrape job listings into Excel, CSV or Google Sheets in a few minutes, without code, using the free Grabby web scraper Chrome extension. It also covers what job boards actually let you take, where the lines are, and how the no-code route compares to writing a script or paying for a data feed.
Who this guide is for
- Job seekers tracking applications across several boards, or watching a saved search for new postings that match their profile.
- Recruiters and sourcers doing quick market research — who’s hiring for a given role, in which cities, at what level.
- People and compensation teams who want a rough pay-range view for a role without buying an expensive labor-market data subscription.
- Founders and analysts sizing a market or a competitor by counting and categorising open roles.
Is it allowed to scrape job boards?
Short answer: it depends heavily on which board, and “the postings are public” is not the same thing as “automated collection is permitted.” A few concrete data points worth knowing before you start:
- Indeed’s terms of service explicitly prohibit automated access to the site, including bots and scraping tools, and Indeed actively monitors for and blocks unauthorized collection.
- LinkedIn has litigated this and won, eventually. The long-running hiQ Labs v. LinkedIn case initially found that scraping purely public profile data wasn’t automatically a computer-fraud crime — but that never meant scraping was allowed. LinkedIn’s terms still prohibited it as a contract matter, and after six years of litigation the case ended in a settlement against hiQ, including a $500,000 judgment and an injunction, and hiQ shut down. LinkedIn is the strictest, most actively enforced board in this space — treat it accordingly.
- Company career pages tend to be far more permissive. Sites built on Greenhouse, Lever, Workday and similar applicant-tracking systems are meant to be found and read by candidates and search engines, and many even expose public job feeds.
- Smaller and niche boards vary a lot. Check the terms page of whichever site you’re using before you rely on it for anything beyond casual personal use.
In practice, most people doing personal job tracking or one-off market research keep things modest: pull a page you’ve already loaded in your own browser (which looks like normal browsing, not a bot farm hammering the server), avoid LinkedIn if you want to stay clearly inside the rules, don’t republish the raw data, and review the terms of any site you use regularly. For commercial or high-volume use, go through an official channel (see the table below) or have a lawyer review the specific terms. This is practical guidance, not legal advice.
No-code vs Python vs official APIs vs paid data
There are four realistic ways to turn job postings into structured data. Here’s how they actually compare:
| Approach | Cost | Coverage | Freshness | Effort | ToS risk |
|---|---|---|---|---|---|
| No-code browser tool (Grabby) | Free in early access | Any board you can browse, list and detail pages | As fresh as your last run | Minutes, point-and-click | Behaves like normal browsing; still review each site’s terms and keep volume modest |
| Custom Python / Scrapy / Selenium script | Free to build, but your time plus proxies or anti-bot services add up | Whatever you code for; breaks when the page markup changes | As fresh as you choose to re-run it | Hours to days to build, then ongoing maintenance | Same exposure as any scraper, and you’re now the one running the infrastructure |
| Official / partner API (aggregator publisher programs, LinkedIn Talent Solutions) | Indeed’s open publisher program is closed; LinkedIn requires a signed partner agreement and a lengthy review; some aggregators (Adzuna, Jooble, Talent.com) still run open programs | Only what the partner exposes — often the partner’s own aggregated postings | Real-time via API | An application or approval process, then a fairly simple integration | Lowest — you’re operating inside the platform’s own rules |
| Paid job data providers (scraping-as-a-service, dataset vendors) | Usage-based, often meaningful at volume | Broad, pre-aggregated across many boards | Depends on the provider’s refresh schedule | Low — you consume an API or a dataset | Shifts to the provider, but check what you’re licensed to do with the data downstream |
What you’ll need
- Google Chrome, Microsoft Edge, or Brave.
- The free Grabby extension — no account, no API key, runs locally.
- A job-board search results page: Indeed, a company careers page, LinkedIn (with the caveats above), or any board you use.
Step 1: Run and filter your search
Search the board for your role and location and apply the filters you care about — remote, salary range, date posted, seniority. Filtering first means every row you scrape is already relevant, instead of cleaning out noise afterward. Scroll once so the first page of results has finished loading.
Step 2: Select the results list
Click the Grabby icon, choose Scrape List, then Select the list and click any one job card. Grabby highlights the whole repeating set and one click grabs them all, auto-detecting the columns: title, company, location, salary or pay range where the board shows one, posted date, and the link to each posting.
Step 3: Load every result — pagination or infinite scroll
Job boards handle “more results” two different ways: numbered pages with a next-page link (classic pagination), or a feed that keeps loading more postings as you scroll (infinite scroll, common on LinkedIn and several modern boards). Grabby handles both: choose Pagination and point at the next-page control once, or choose Auto-scroll for a feed. Set a sensible maximum — pages or scrolls — and hit Start. Grabby walks the full result set and collects every job card along the way.
Step 4: Pull full descriptions with detail-page scraping
The results list only ever shows a summary. The full job description, requirements, benefits and application details live on each posting’s own page. This is where detail-page scraping earns its keep: hand Grabby the column of job links you already captured, and it opens each posting in turn, pulls the description and any other fields you point at, and merges everything back into the matching row — by link, so nothing gets mismatched. A list of job cards becomes a full dataset you can keyword-search in Excel.
Step 5: Clean up in the editable table
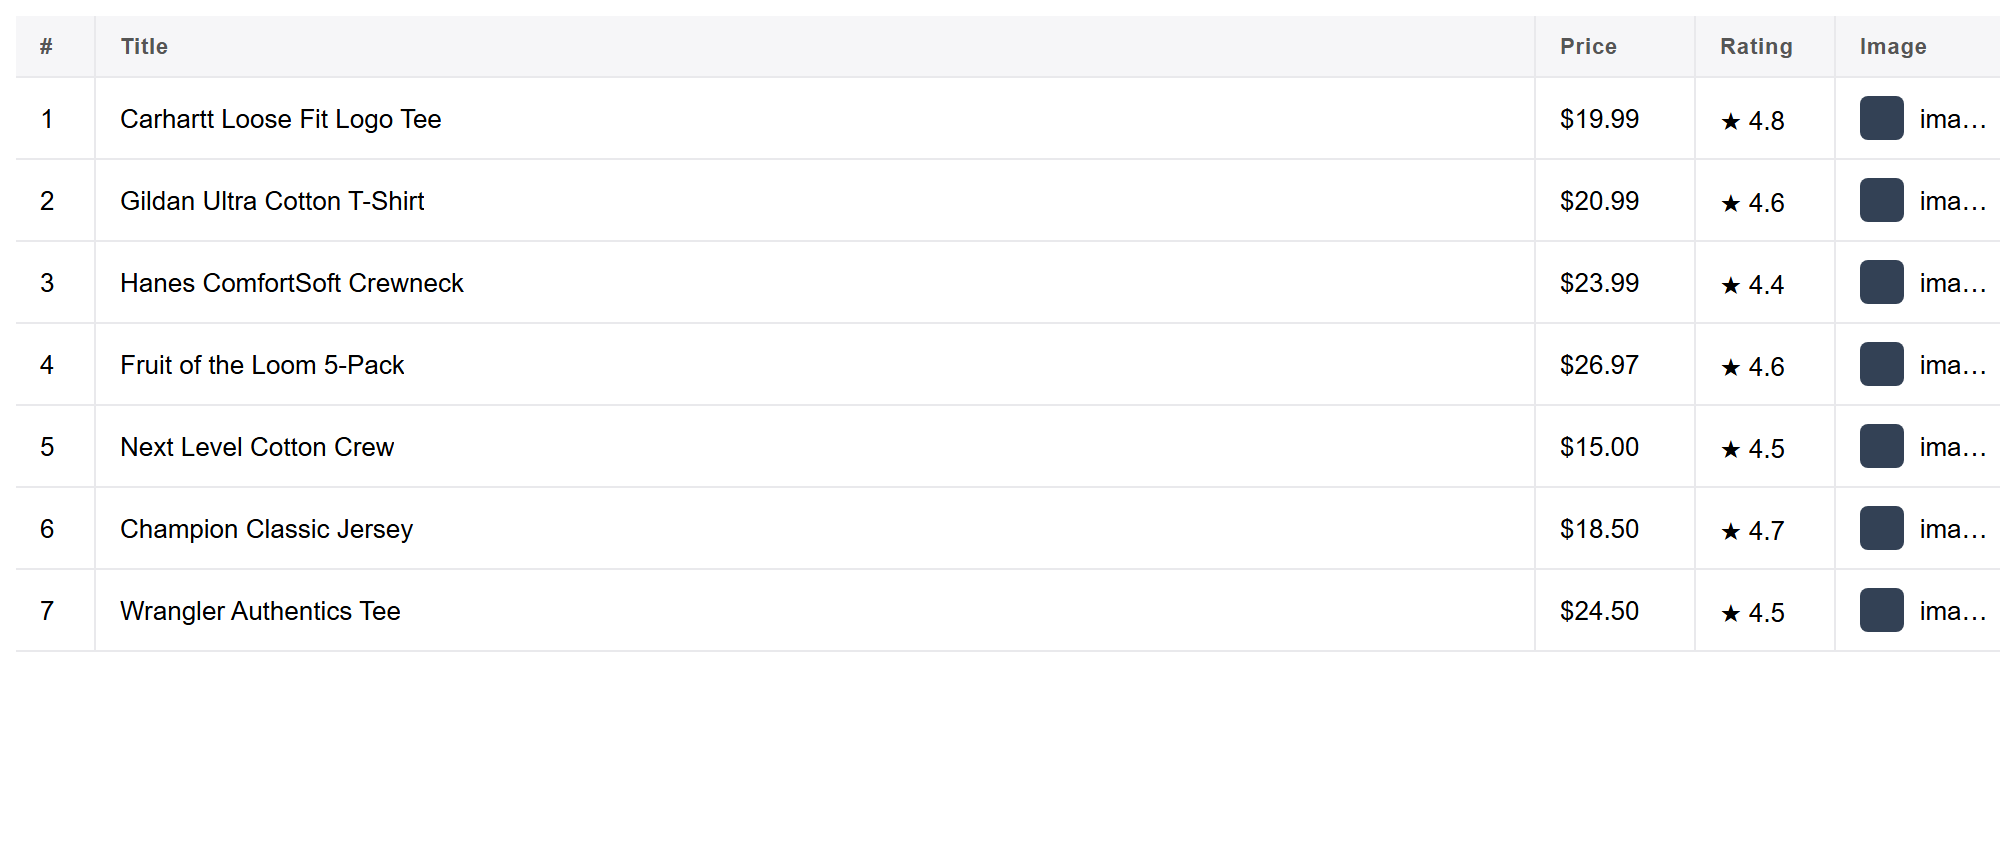
Your results open in an editable table before you export anything. Remove duplicate rows (the same posting often appears more than once across pages, or gets reposted), delete empty rows and columns, rename headers, hide columns you don’t need, and sort by salary or posted date to see what’s newest or best-paying first.
Step 6: Export to Excel, CSV, JSON — or Google Sheets
When the table looks right, Export to CSV, Excel-ready TSV or JSON, or copy it straight into Google Sheets. Everything runs and stays on your machine — nothing is uploaded to a server in between.
Going further: parsing salaries, dedup and refresh cadence
Turn pay ranges into real numbers. Boards show salary in wildly inconsistent formats — “$75,000–$95,000/yr”, “$35/hr”, “Up to $120K”. Grabby captures the text as shown; once it’s in a spreadsheet, strip the currency symbols and commas and split minimum and maximum into two numeric columns (Excel’s Text to Columns, or a SUBSTITUTE/VALUE formula, both work) so you can actually sort, filter and average by pay.
Dedupe across repeated searches. If you run the same saved search weekly, postings will repeat. The job link is a stable per-posting key — combine your exports and remove duplicate rows on that column, or keep one running master sheet and only append rows whose link you haven’t seen before.
Set a refresh cadence. For personal tracking, re-running the same search every few days and diffing against your last export (new links = postings you haven’t seen) is enough to catch new openings early. For recruiter market research, weekly or monthly pulls are usually plenty to see hiring trends shift without repeatedly hitting the same pages.
Go area-by-area. Most boards cap how many results a single search will return. Rather than one huge national query, run several narrower searches by city, region or role and merge the exports — you end up with more total coverage, and each individual pull is faster and lighter.
Real-world use cases
- Job seekers keeping one master spreadsheet of every role applied to, with status, salary and the original link, instead of losing track across browser tabs.
- Recruiters and sourcers mapping which companies are actively hiring for a role right now, and at what seniority.
- Compensation and People teams sanity-checking a pay band against what’s actually being advertised for similar roles nearby.
- Analysts and founders tracking a competitor’s headcount growth by watching how many, and which, roles they post over time.
Frequently asked questions
Is it really free? Yes. Grabby is free while in early access, with every feature unlocked and no sign-up. It runs locally in your browser.
Which fields can I capture from the results list? Whatever the search results show: job title, company, location, salary or pay range where the board displays one, posted date, and the link to each posting.
Can I get the full job description and requirements too? Yes — give Grabby the column of job links and it opens each posting, pulls the description and requirements, and merges them back into the matching row.
Can it scrape every page of results? Yes. Use Pagination for numbered pages or Auto-scroll for feeds that load more as you scroll, up to a maximum you set.
Is it allowed to scrape job boards like Indeed or LinkedIn? Both restrict automated access in their terms, and LinkedIn has enforced that through litigation. Company career pages are generally more permissive. Keep runs modest, read the terms of the site you’re using, and don’t resell the data. Not legal advice.
Does Grabby get past CAPTCHAs or logins? No. It reads the page already loaded in your browser and doesn’t solve CAPTCHAs or bypass bot detection. A block or challenge is a signal to slow down.
Can I avoid duplicate postings across searches? Yes — use the job link as a unique key and dedupe on it, either in Grabby’s editable table or after combining exports.
Can I export to Excel, Google Sheets, or another format? Yes. CSV, Excel-ready TSV, JSON or Markdown, or copy straight into Google Sheets — all generated locally.
More ways to build datasets
The same select, paginate, clean and export flow works on any list. See how to scrape any website to Excel, turn a directory into a lead list, or pull a table from any web page the same way.